Serve it. One API for every model you use.
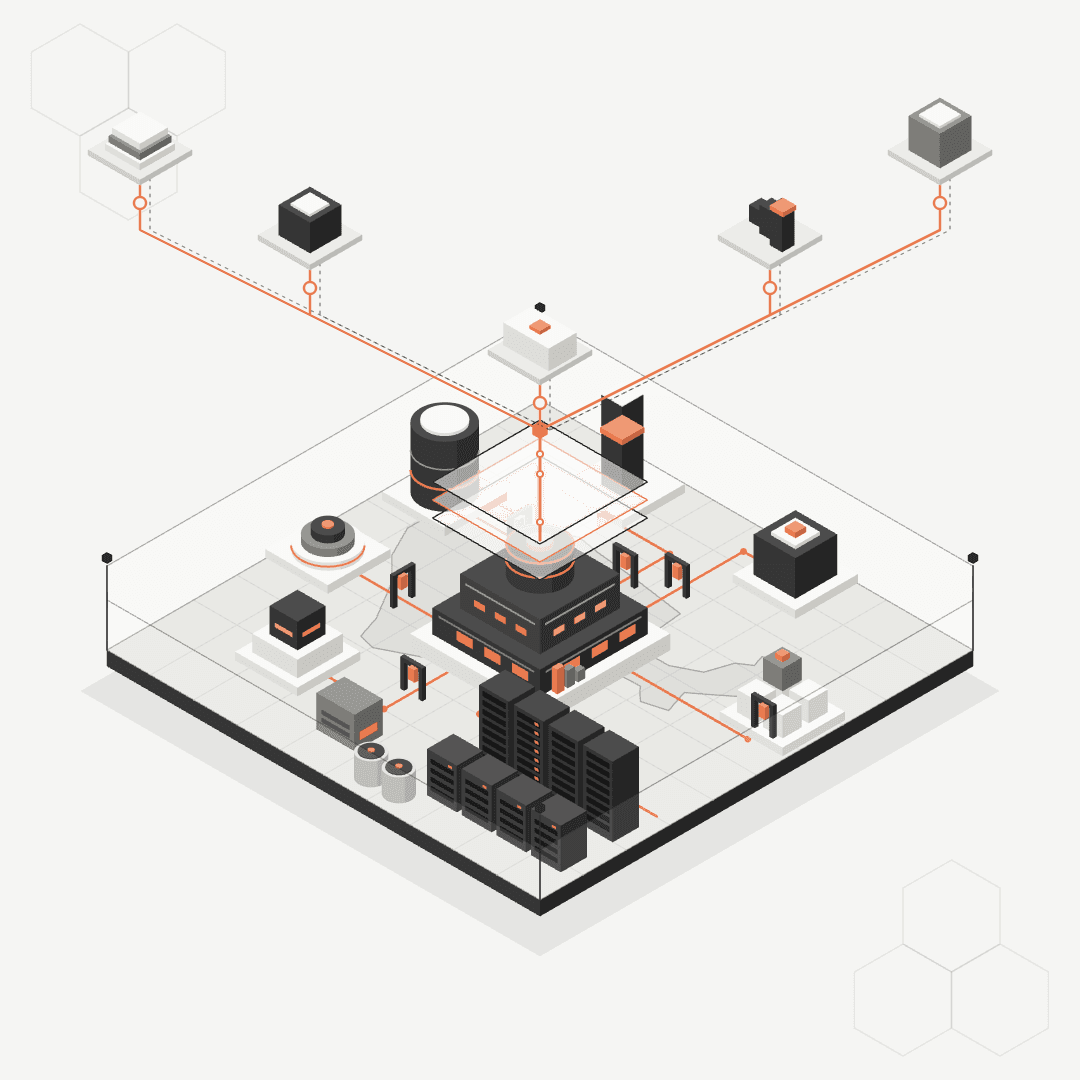
Sovereign AI infrastructure platform
Trusted by sovereign AI operators and enterprise IT.
Stixor AI Hub is Stixor's sovereign AI infrastructure platform. It unifies model access, fine-tuning, and governance into one control plane, meters every call per tenant, and enforces hard budget caps before they reach the model, not after. Built for NVIDIA and Huawei Ascend.
Tokens blocked by hard caps:
4,281,900,527
One OpenAI-compatible API in front of every model.
Hard spending limits enforced at the API, pre-call.
Every token and accelerator-second counted per key.
Per-tenant invoiceable records for chargeback.
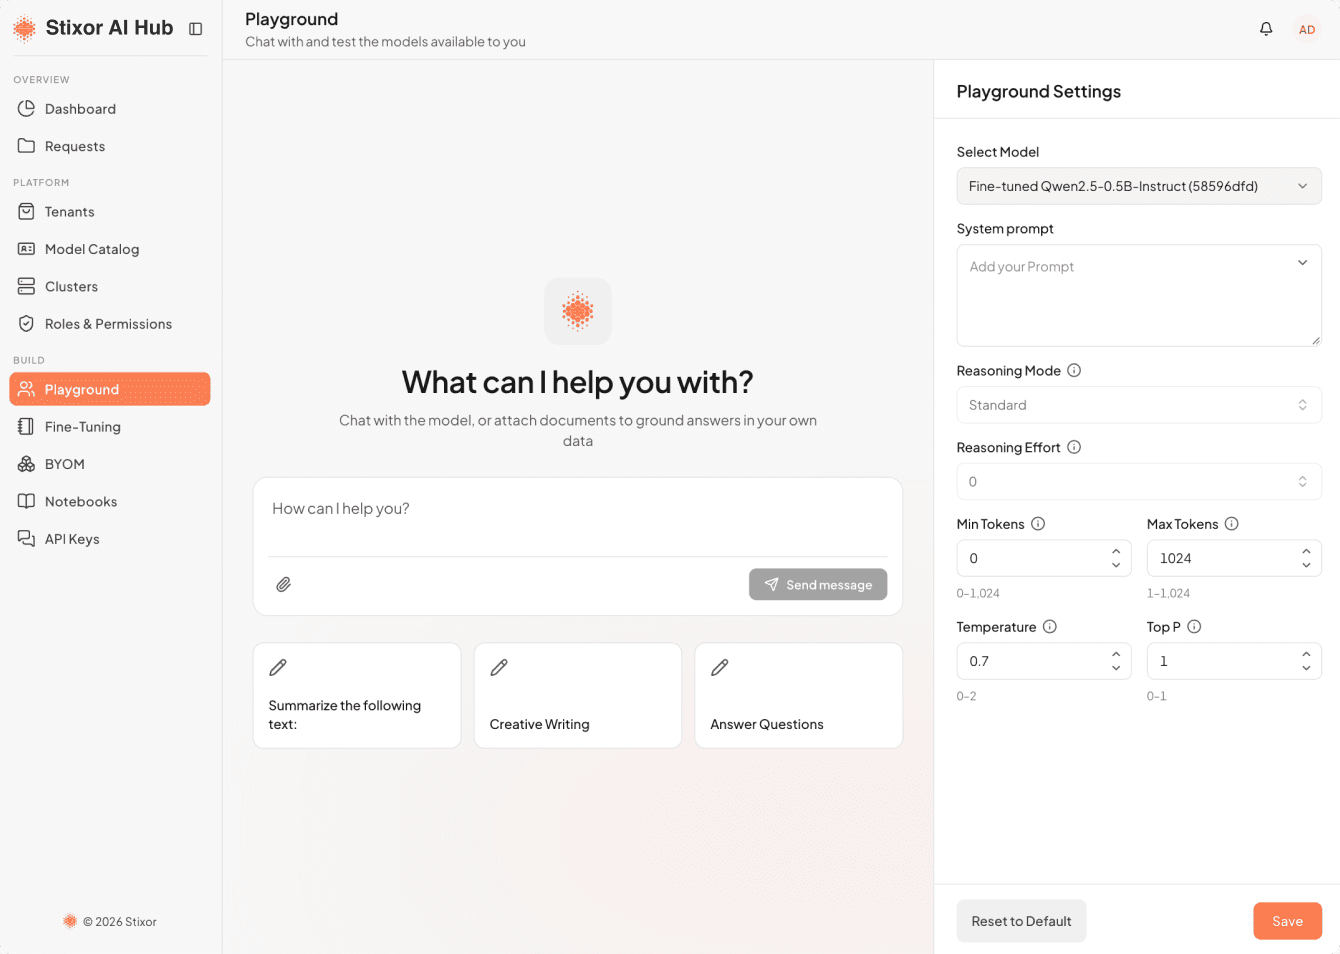
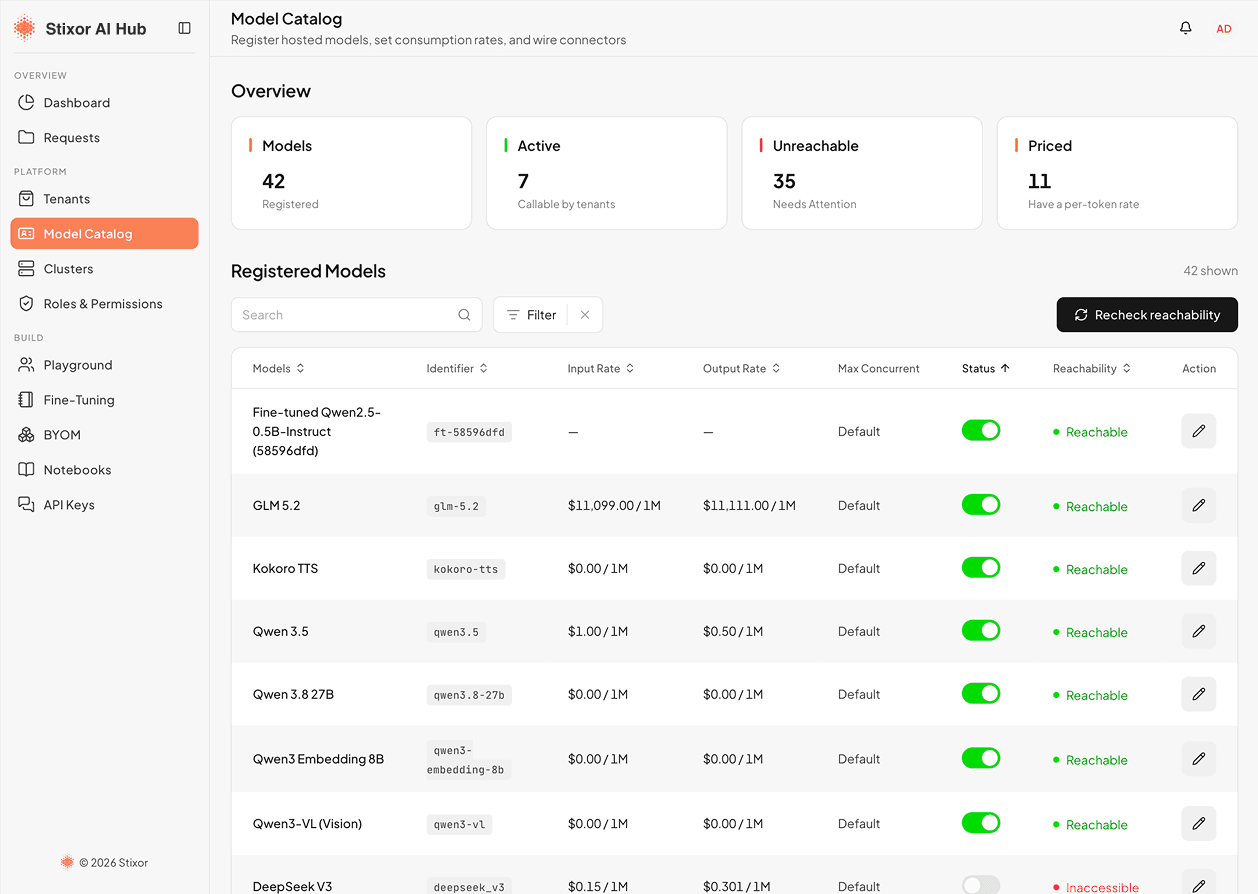
Stixor AI Hub exposes one OpenAI-compatible API in front of every model you serve. Existing applications migrate with a URL change. Open-weight models on your servers and external providers route through the same endpoint.
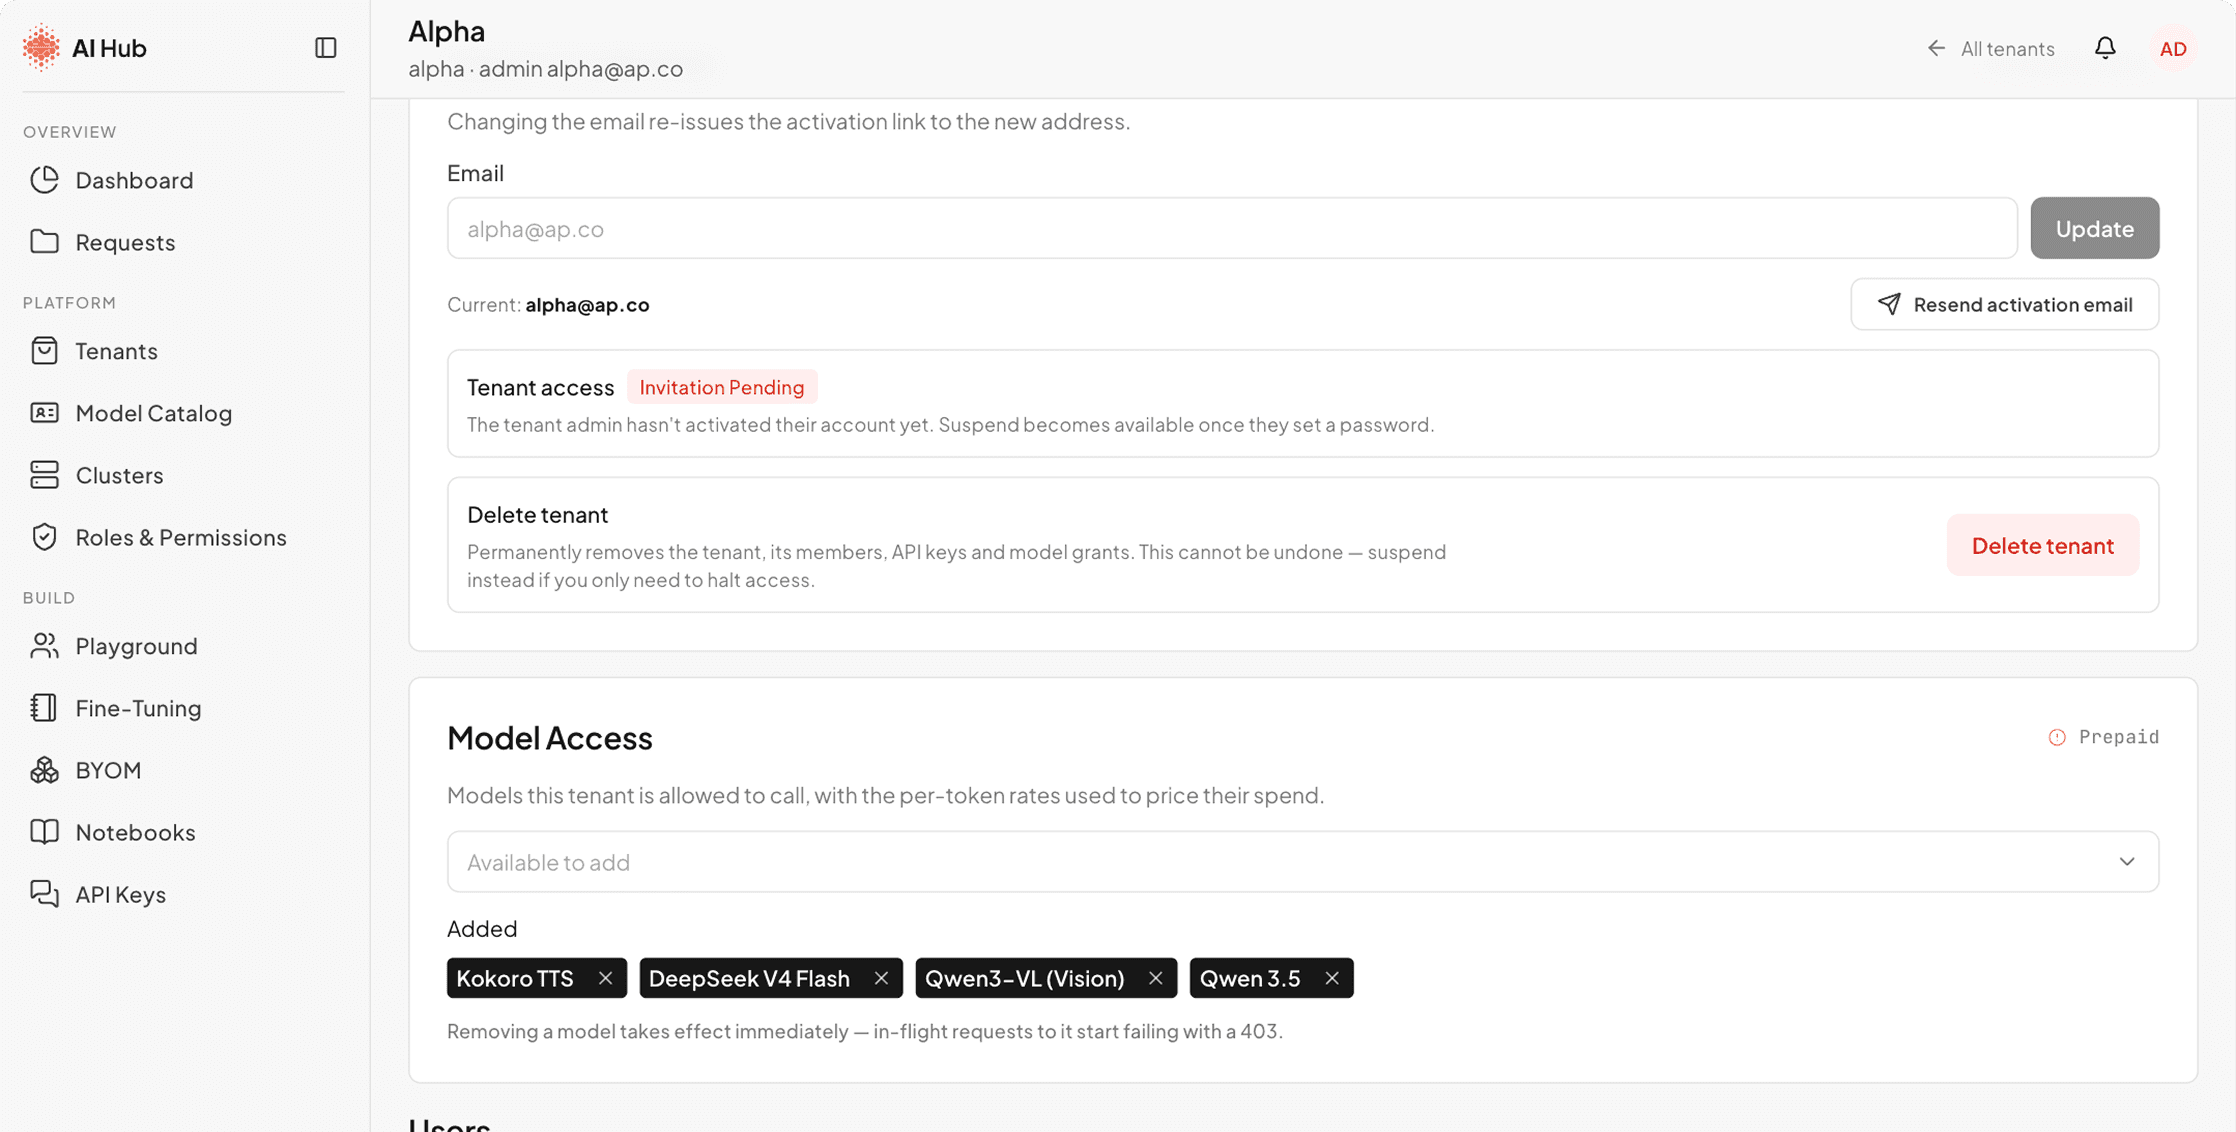
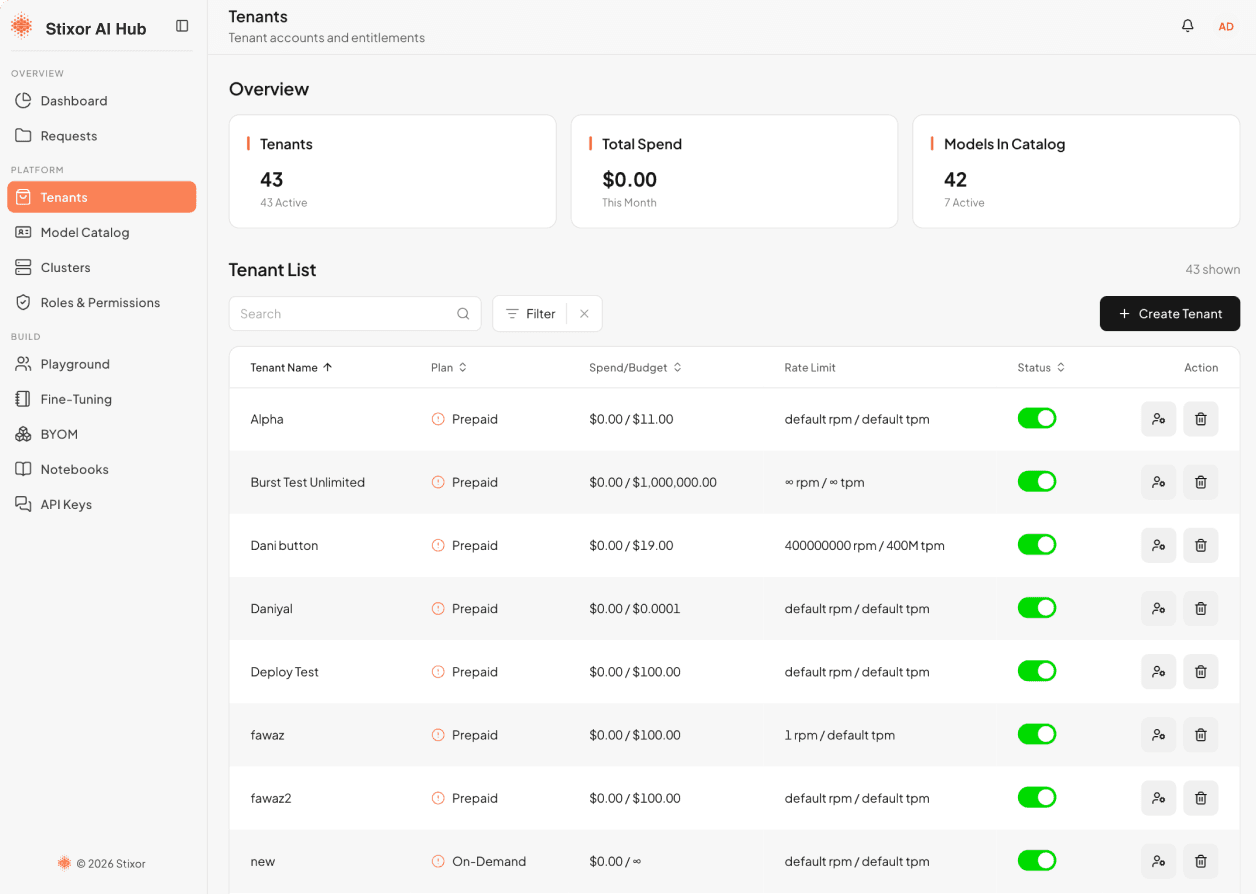
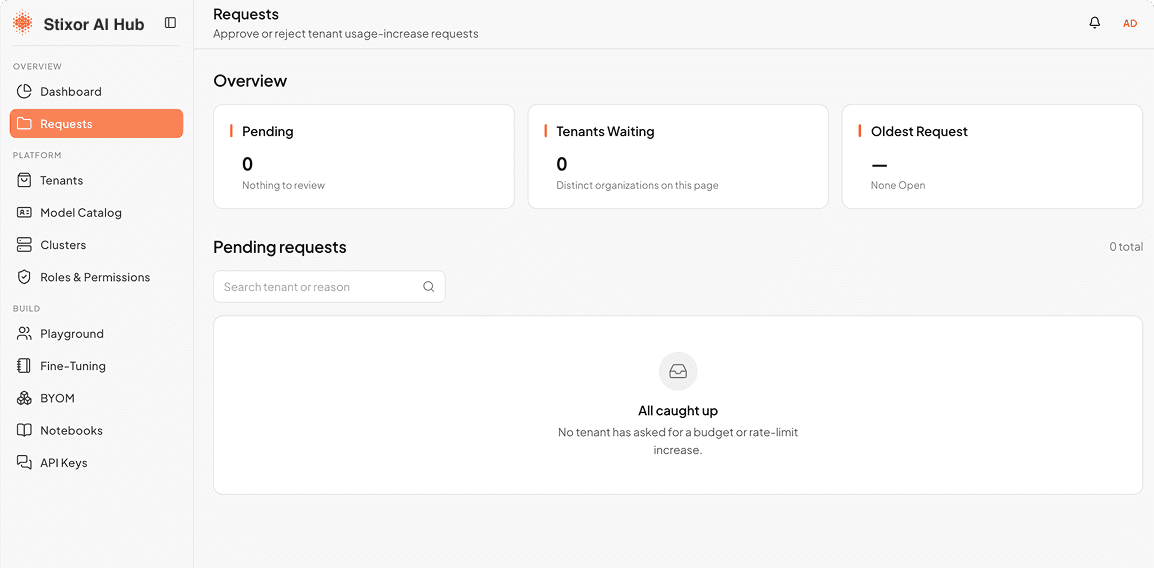
Every department or application becomes a tenant with its own API keys, rate limits in requests and tokens per minute, and a model entitlement list. Tenants self-serve keys from the console. Admins control the catalogue and limits.
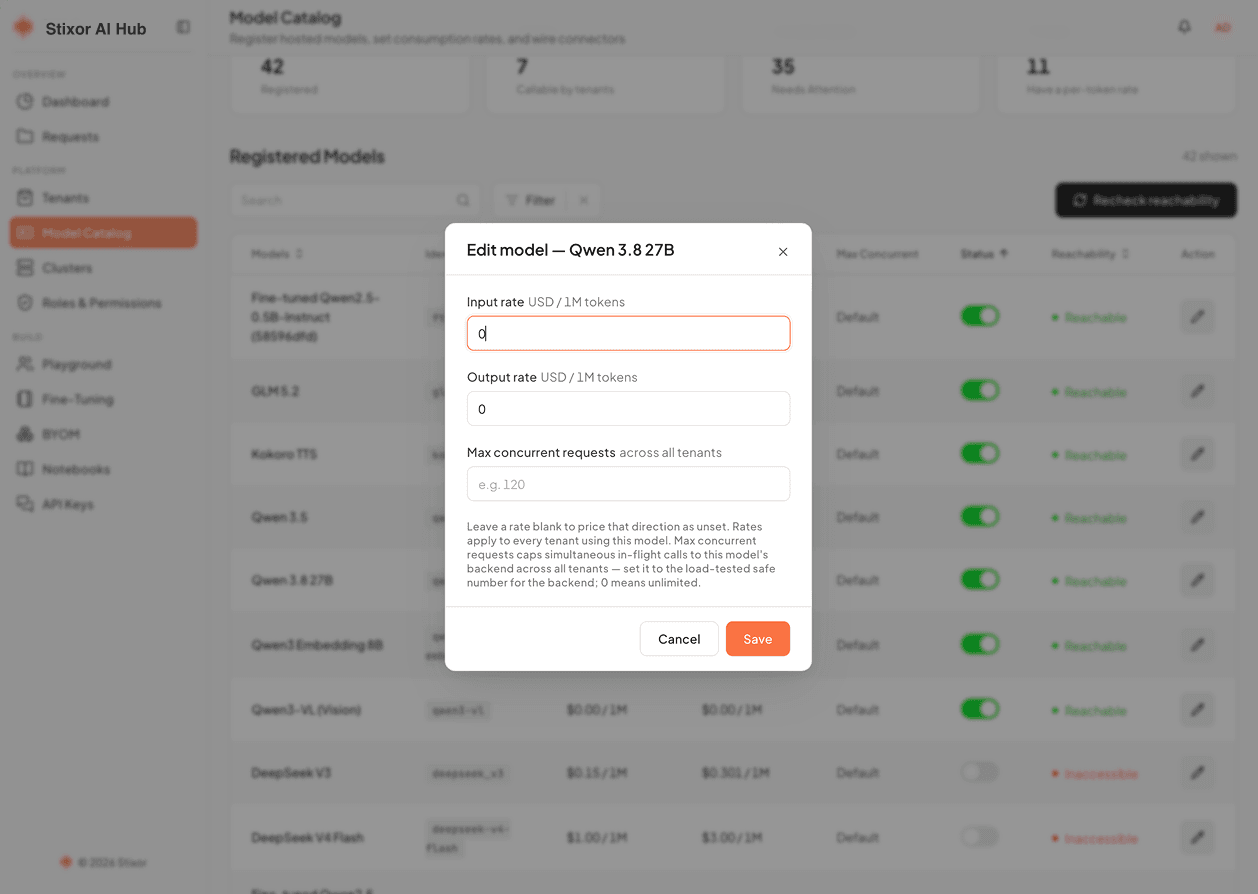
Teams set a soft budget cap. Admins set a hard cap that cannot be exceeded. Both are enforced at the API before the call reaches the model. Nothing runs past the limit, so nothing is billed in error or reconciled a month later.
Every call is metered per key with tokens in, tokens out, cost, and time. Per-tenant dashboards show spend in real time. Usage records export as invoiceable line items for internal chargeback or external customer billing.
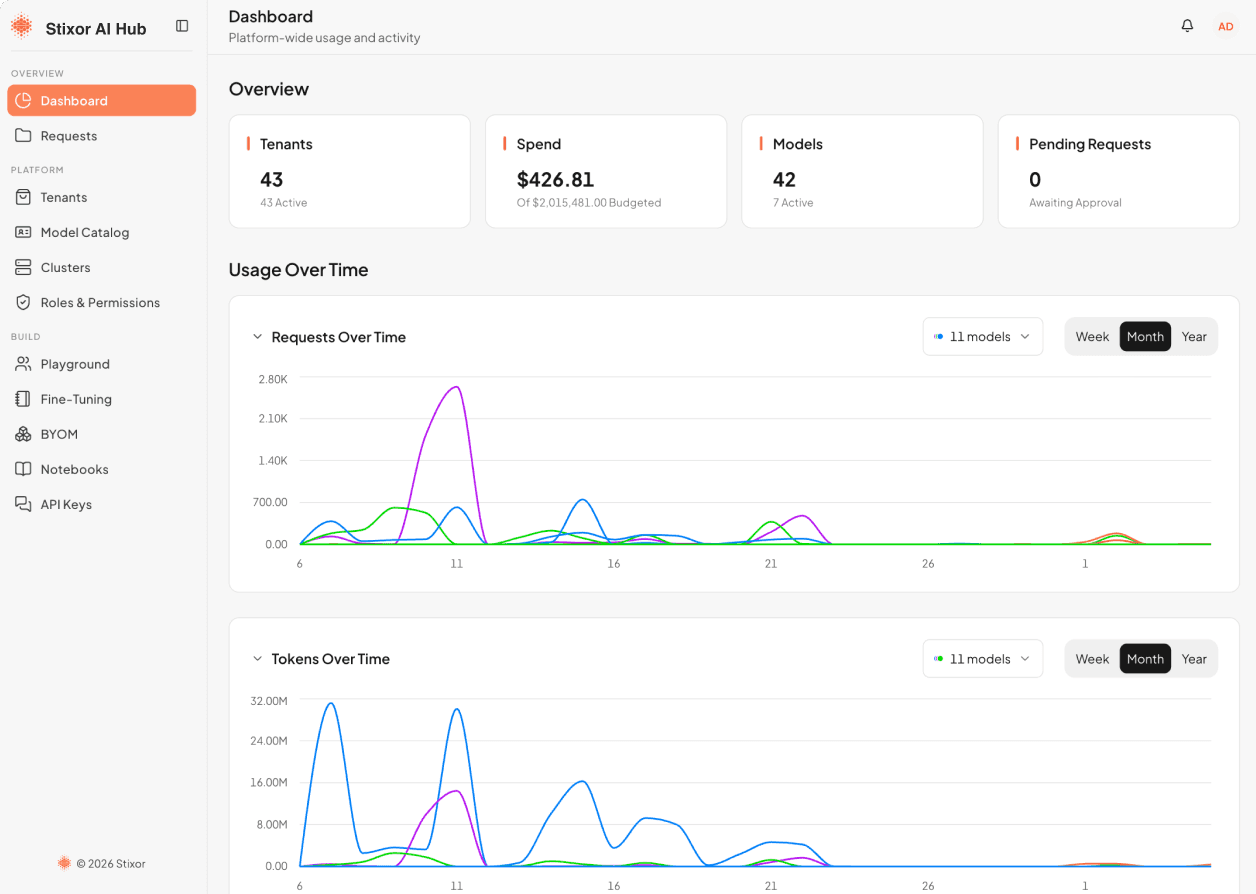
Model-as-a-Service serves a catalogue through one API. Platform-as-a-Service adds hosted notebooks, training jobs, LoRA, QLoRA, full fine-tuning, no-code tuning, and a model registry that deploys to the same API in one click.
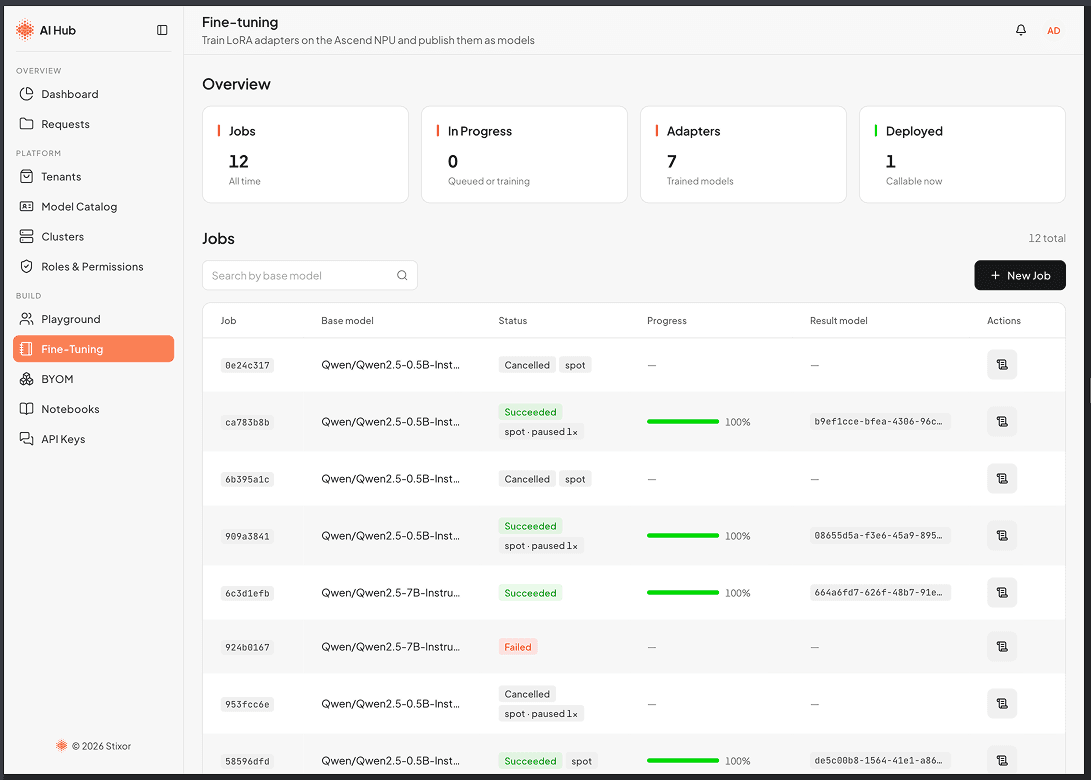
Teams set a soft budget and get warnings. Admins set a hard cap that blocks the call when hit. Both are checked at the API before the request reaches the model, so no tokens are generated and no cost is incurred past the limit.
Models and Variants served
Accelerator vendors unified
Tokens generated past a hard cap
Tenants per deployment
Deployment: on-prem or private cloud
Platform uptime
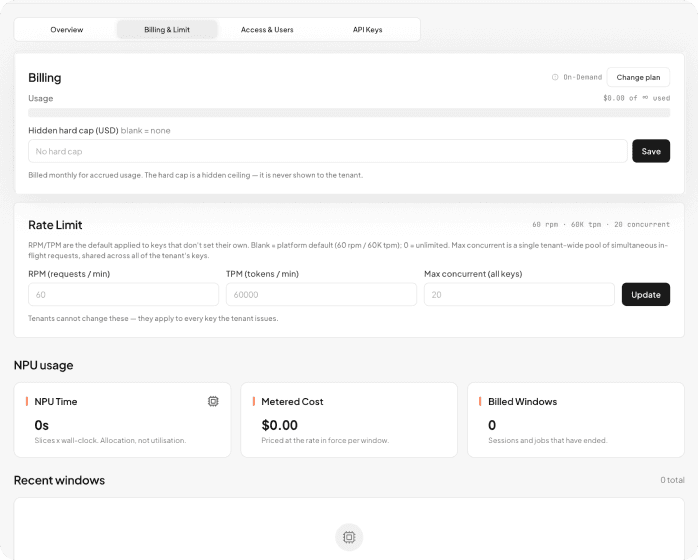
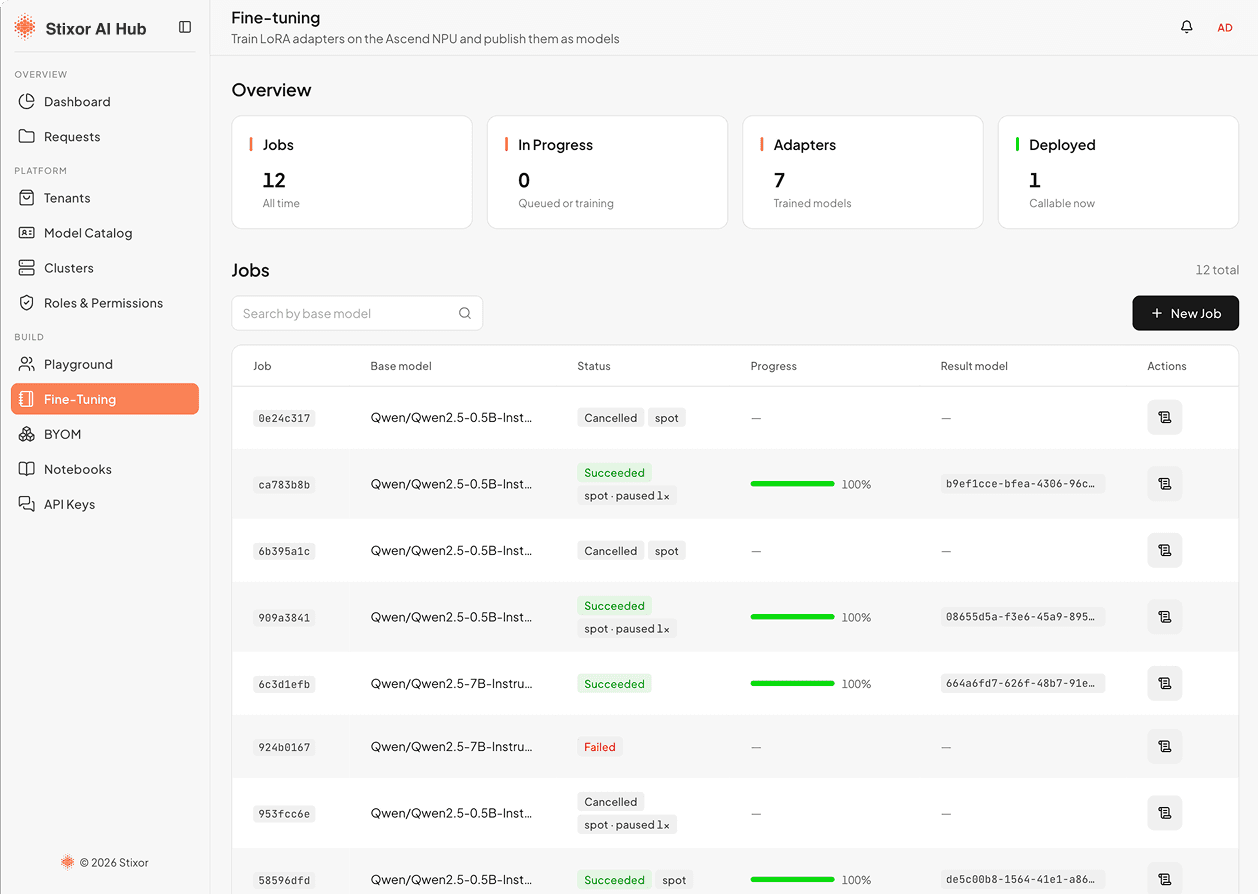
One platform. Every team.
Stixor AI Hub ships the catalogue, controls, metering, and build tools in one deployment.
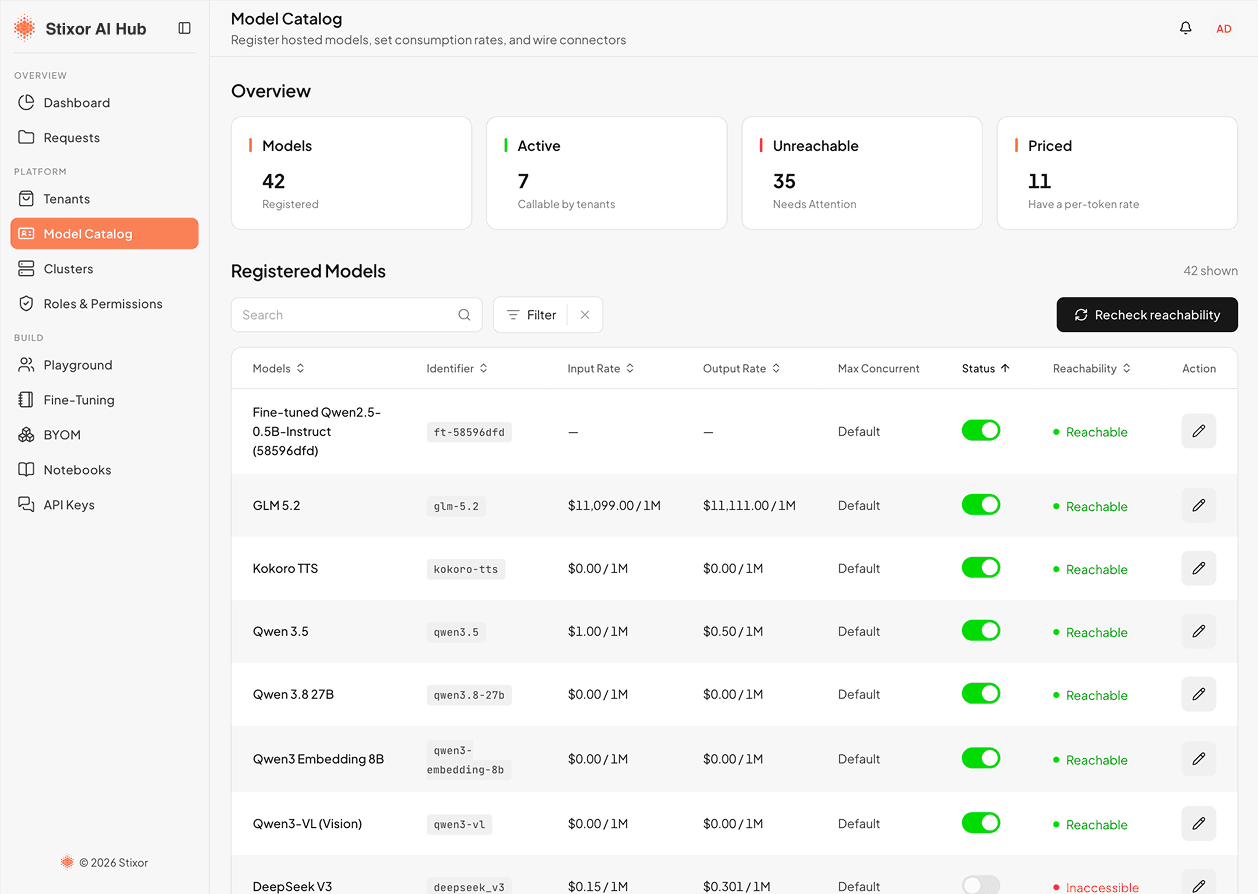
A catalogue served from one shared accelerator pool. Popular models stay always-on, mid-demand models share cards, long-tail models load on request. Many fine-tuned variants are served from a single base model.
BLOGS

Muhammad Rizwan
07-Oct-2026
Muhammad Rizwan
09-Oct-2026
Partner with us to understand your business goals and create solutions that drive measurable results. Reach out today and take the first step toward transforming your data into a strategic asset with Stixor.
CONTACT US
FAQs
Stixor AI Hub is Stixor's sovereign AI infrastructure platform. It unifies model access, fine-tuning, and governance into one control plane, meters every call per tenant, and enforces hard spending caps before each call reaches the model. Built for NVIDIA ,Huawei Ascend,AMD and other 7+ Accelerator.
Hard caps are enforced at the API before each call reaches the model, not reported after. Teams set a soft budget cap. Admins set a hard cap that cannot be exceeded. When a tenant hits the limit, the request is blocked and no tokens are generated past the cap.
NVIDIA GPUs, AMD GPUs, and Huawei Ascend NPUs, plus T-head, Hygon, MetaX, Moore Threads, Cambricon, and Iluvatar. Nine accelerator families run in the same deployment. The accelerator is a job attribute, not a platform choice, so mixed fleets work without lock-in.
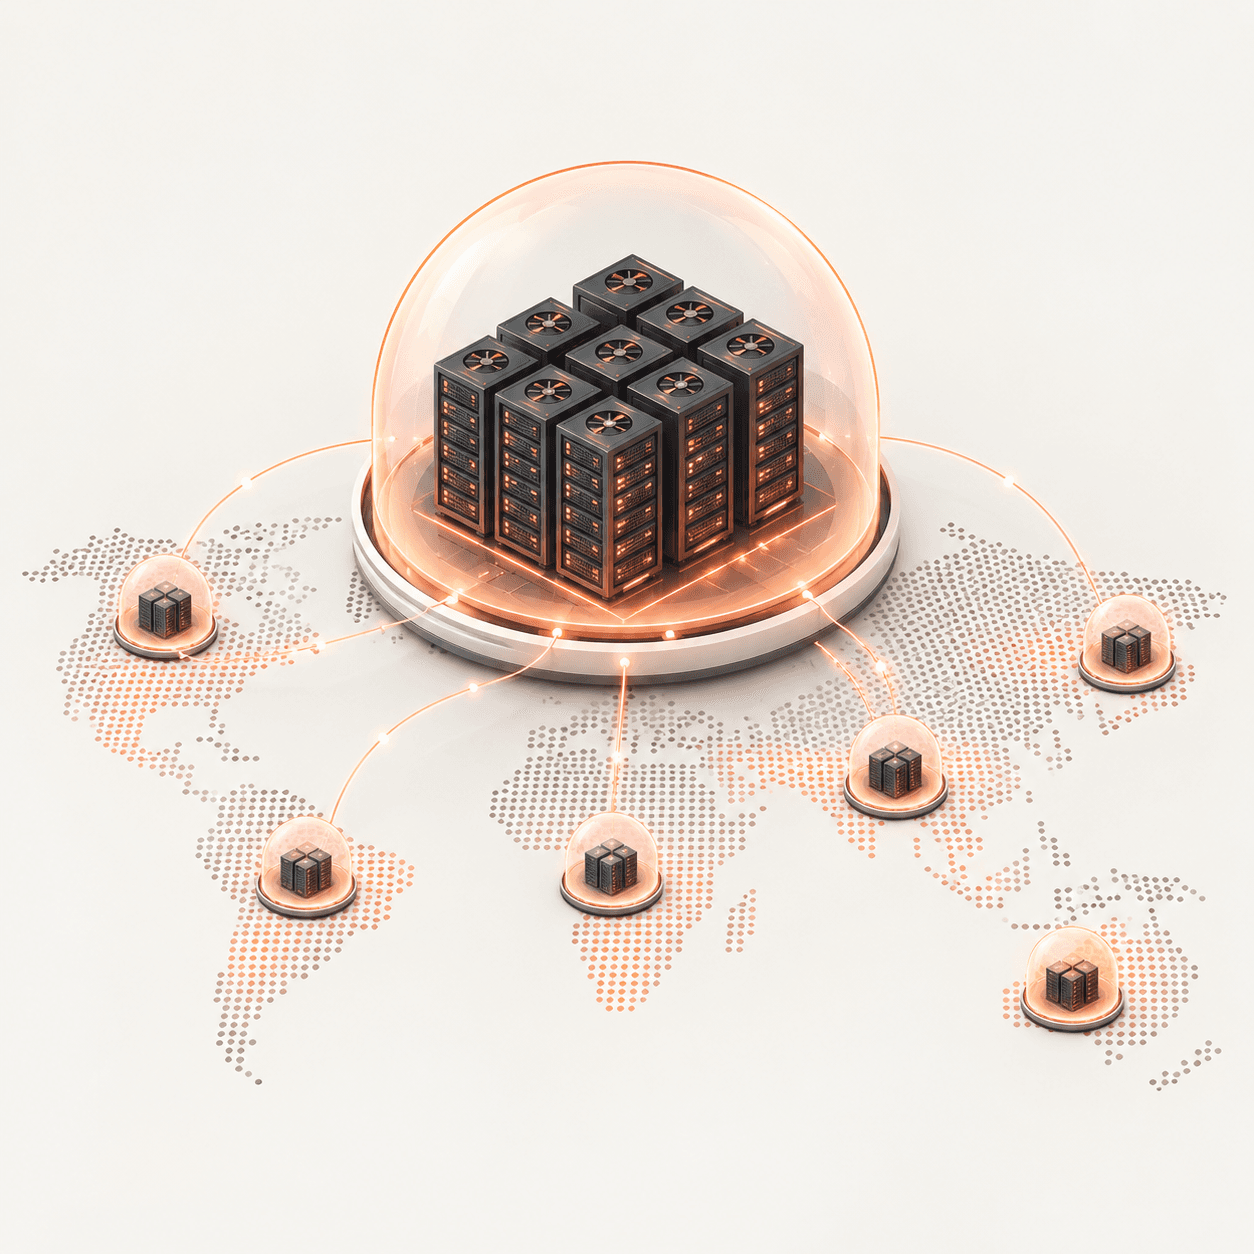
Yes. Stixor AI Hub runs entirely inside your own environment: on-premises, in your private cloud, or air-gapped where regulation requires it. No data leaves your infrastructure. This is why sovereign AI operators like Sky47 run on Stixor AI Hub.
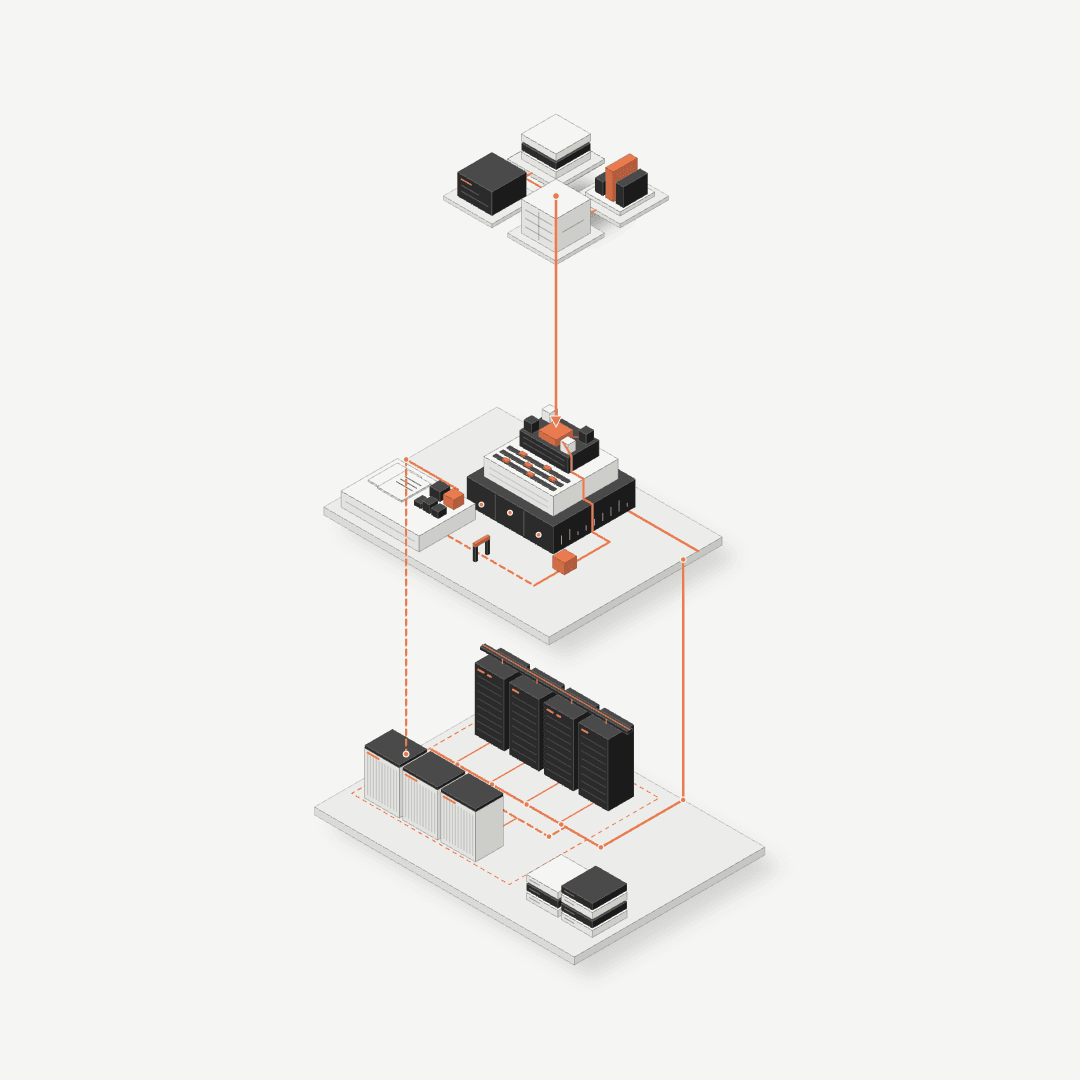
Yes. Stixor AI Hub ships Kubernetes-native with Docker, Podman, and Helm support. It installs onto an existing cluster or ships with its own. Prometheus and Grafana cover observability. Tenant isolation is enforced at the namespace level.
Yes. Platform-as-a-Service ships hosted Jupyter notebooks, bring-your-own-container training jobs, and curated recipes for LoRA, QLoRA, and full fine-tuning, plus no-code tuning. The model registry deploys any fine-tuned model to the inference API with one click.
Yes. Install on your accelerator servers and you get a model catalogue, OpenAI-compatible API, tenant sign-up, prepaid credits, hard caps, and invoice-ready billing. Customers sign up, generate keys, call models, and get billed, without you building any of it.
From small to large scale enterprises, we deliver next-gen AI, data engineering, and actionable insights.
SERVICES
AI & ML Solutions
Cloud Strategy Management
Data Solutions & Advanced Analytics
Data Center Consulting & GPU Services
On-Prem & Predictive Analytics Solutions
MLOps Implementation Services
Data Engineering & Architecture
Enterprise Technology Consulting
Data Governance Compliance
Web Development
App Development
Software Development
Game Development
AR/VR
Product Design & UX
Blockchain Development
CTO & IT Talent Services
QA Testing & Automation
INDUSTRIES
CASE STUDIES