
Data Engineering and Architecture Services for the Enterprise
Analytics and AI are only as good as the data infrastructure underneath. When pipelines break silently, warehouses miss refreshes, and new sources take weeks to integrate, the problem is your data engineering. Stixor builds the pipelines, warehouse and lakehouse architecture, and orchestration that keep enterprise data reliable, governed, and fresh.

What Data Engineering Services Include
Data engineering is the discipline that designs and operates the infrastructure that moves, transforms, stores, and serves data across an organization. Pipelines are automated workflows that ingest data from source systems, transform it, and load it into warehouses or lakes on a governed schedule. Stixor delivers the full chain across pipeline development, data architecture, ingestion, transformation, streaming, integration, orchestration, data quality, observability, and governance.
Why Choose Stixor Data Engineering Team
We design scalable data architectures and automated pipelines that support analytics and AI initiatives while ensuring data integrity, security, compliance, and performance across enterprise environments
WHY US
Built for Real Data
Source systems have inconsistent schemas, undocumented field changes, duplicates, and mixed timestamps. Our pipelines handle real production traffic with validation, error handling, and dead letter queues.
Fit for Your Query Patterns
Snowflake, Databricks, BigQuery, and Redshift each solve different problems well. We recommend on your data volumes, query patterns, team skills, and budget, not on the platform we know best.
Silent Failure Prevention
Silent pipeline failures quickly undermine trust in analytics. Layered monitoring inside every pipeline (schema validation, freshness checks, anomaly detection, and reconciliation) catches failures before they hit downstream.
A Platform, Not a Dependency
Every pipeline, transformation, and workflow ships with documentation covering business logic, source connections, and monitoring. Knowledge transfer is a deliverable, not a farewell email.
CAPABILITIES
Data Engineering Capabilities
Capabilities span the lifecycle from pipeline development through architecture, streaming, integration, quality, and governance.
Pipeline Development and Automation
Automated pipelines that extract, validate, transform, and load data on a reliable, monitored schedule. ETL when transformations happen before landing, ELT when the warehouse can transform in place.
- Batch and incremental ingestion from databases, APIs, files, SaaS
- Change data capture and analytics engineering with dbt
- Validation, dead letter queues, and alerting on failed records
Warehouse and Lakehouse Architecture
The centralized analytical layer, whether a structured warehouse with dimensional models or a lakehouse combining flexible storage with warehouse governance.
- Dimensional modeling with fact tables and slowly changing dimensions
- Lakehouse on Databricks, Snowflake, BigQuery, or Redshift
- Zone design across raw, cleaned, curated, and consumption layers
Real-Time and Streaming Pipelines
Some data cannot wait for overnight batch. Streaming pipelines ingest events, process them in flight, and deliver to analytical and operational systems with sub-minute latency.
- Event streaming on Kafka, Kinesis, or Pub/Sub
- Stream processing with Flink, Spark Structured Streaming, or Kafka Streams
- Hybrid batch and streaming architectures
Data Integration Across Systems
Enterprise data sits across ERP, CRM, marketing, operational databases, and third-party APIs that were never built to work together. Integration layers connect them, resolve entity matching, and handle schema conflicts.
- Source integration across databases, REST APIs, SFTP, and SaaS
- Entity resolution across inconsistent identifiers
- Fivetran, Airbyte, or custom connectors where needed
Orchestration and Workflow Management
Pipelines have dependencies. Dashboards wait on source tables that wait on upstream extractions. Orchestration keeps that complexity observable and recoverable.
- Airflow, Dagster, or Prefect
- DAG design with dependencies and failure alerting
- SLA monitoring with escalation on missed windows
Data Quality and Observability
Frameworks that detect schema changes, freshness issues, anomalies, and broken dependencies before they hit downstream analytics, using Great Expectations, Soda, dbt tests, or Monte Carlo.
- Schema, freshness, and referential integrity checks
- Volume and distribution anomaly detection
- Data lineage from source to metric

Discuss Your Data Engineering Use Case
A first pipeline or a full data platform rebuild. Either way, we engineer the foundation your analytics and AI teams depend on.
What We Actually Deliver
We deliver ETL pipelines, scalable architectures, system integrations, secure storage solutions, and continuous monitoring to ensure reliable data flow and analytics-ready infrastructure.
Deliverable
01
Discover and Assess
We start with your data landscape, analytical requirements, and the problems your current infrastructure cannot solve. Nothing moves until you approve the architecture and roadmap.
- Data source inventory across systems, freshness, and reliability
- Pipeline audit for fragile, slow, or silently failing feeds
- Architecture blueprint with technology selection and cost model
02
Architect and Build
We build the platform: warehouse or lakehouse, ingestion pipelines, transformation layers, orchestration, quality checks, and monitoring. Your data engineers work alongside ours.
- Warehouse or lakehouse with dimensional models and governed zones
- Pipeline development with extraction, transformation, and validation
- Orchestration with scheduling, dependencies, and alerting
03
Migrate and Validate
The platform goes live. We migrate workloads, validate accuracy through automated reconciliation, deploy monitoring, and train your team.
- Workload migration with parallel runs and reconciliation against legacy outputs
- Data validation across row counts, aggregations, and business logic
- Monitoring across pipeline health, freshness, quality, and SLAs
04
Operate and Extend
We monitor reliability, optimize compute cost, onboard new sources, and help your team develop the practices that make data engineering sustainable.
- Pipeline reliability monitoring with incident tracking
- Query and compute cost optimization
- New source integration and use case expansion
INDUSTRIES
Data Engineering Work Across Industries
Stixor applies data engineering across industries with complex data, integration, analytics, and compliance requirements.

Enterprise AI Agent
Stixor delivers AI-driven solutions for Enterprise AI Agents, enhancing system monitoring, automating responses, and improving operational efficiency. Our platforms provide intelligent decision support, real-time anomaly detection, and workflow automation driving measurable ROI and enabling mission-critical business operations.

Fitness
Developed AI-powered monitoring solutions to detect abnormal user activity, device data inconsistencies, and performance trends. Improved personalization, data accuracy, and user engagement while enabling fitness platforms to deliver safer, smarter, and more adaptive health experiences.

Legal Tech-SaaS
Built intelligent anomaly detection solutions for legal SaaS platforms to identify unusual case activities, billing inconsistencies, and compliance risks. Enhanced workflow automation, reduced manual reviews, improved data accuracy, and strengthened trust by enabling real-time insights for legal teams and enterprises.
Technology Stack
We choose tooling based on your data, team, infrastructure, operating model, and budget rather than forcing a fixed technology stack.
TOOLS USED

Apache Kafka

AWS SageMaker
Elasticsearch
Kubernetes

Docker / K8s
Node.js

Node JS

PostgreSQL

OpenStack
CASE STUDIES
Data Engineering Case Studies
How we have helped enterprises replace fragile, manual data processes with governed, automated platforms.
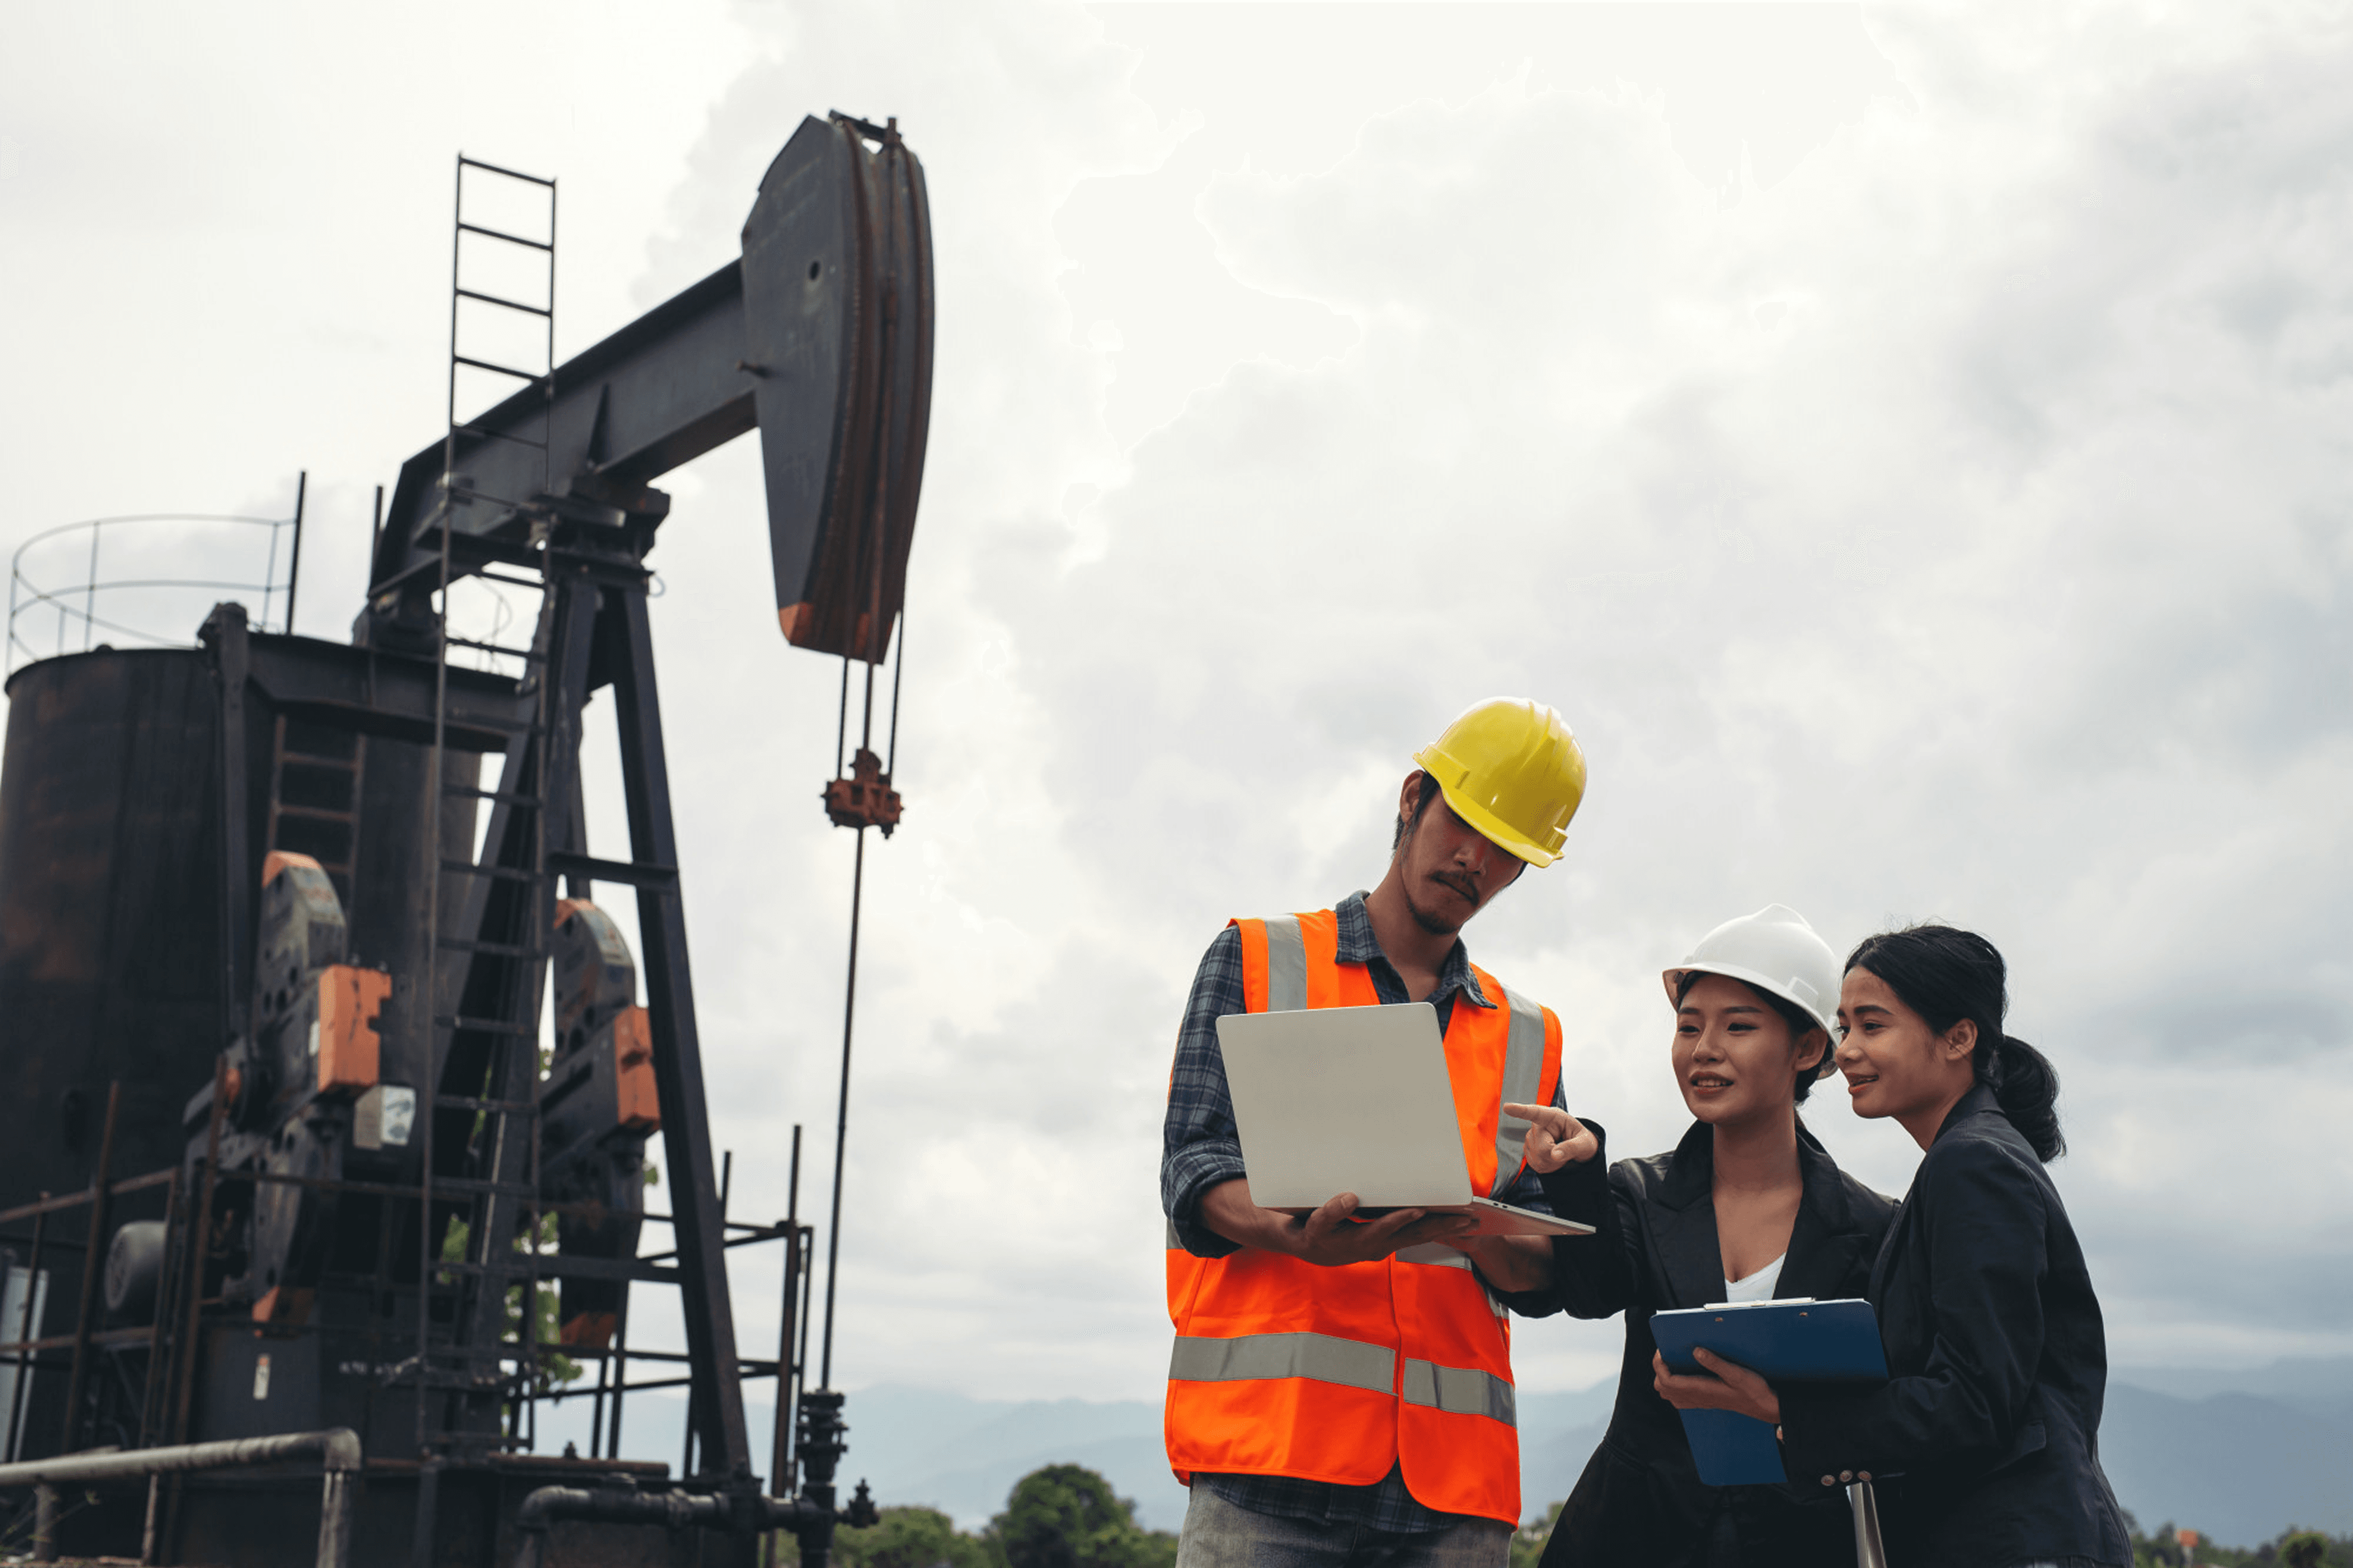
Centralizing Corporate Intelligence with GenAI
Our AI-powered enterprise knowledge platform enables Mari Energies Limited AI Chatbot, an advanced virtual assistant designed for engineers. Cutting-edge LLM, provides instant, accurate responses to technical queries, enhancing troubleshooting efficiency, reducing downtime, and centralizing technical documents.

Automated Customs & Import/Export Compliance
Stixor developed EMT.AI, an AI-powered customs assistant that automates HS code identification, duty/VAT calculations, and document generation. The platform centralizes compliance workflows, reduces errors, accelerates processing, and replaces fragmented portals and broker dependency with a single reliable interface.

High-Performance GPU Data Center Architecture
Stixor developed a multi-vendor GPU cloud platform to provide organizations with high-performance AI infrastructure capable of handling diverse AI/ML workloads efficiently. Supporting Huawei Ascend and NVIDIA GPUs, the platform enables enterprises and public-sector organizations to develop, train, and deploy AI models quickly, securely, and cost-effectively.
Get in Touch with Stixor
Partner with us to understand your business goals and create solutions that drive measurable results. Reach out today and take the first step toward transforming your data into a strategic asset with Stixor.
CONTACT US
What Our Clients Say
TESTIMONIALS
Frequently Asked Questions
FAQs
Stixor provides data engineering services across data pipeline development, ETL and ELT, data warehouse and lakehouse architecture, real-time streaming, enterprise data integration, workflow orchestration, data quality, observability, governance, and data platform modernization.


Discuss Your Enterprise Use Case
From small to large scale enterprises, we deliver next-gen AI, data engineering, and actionable insights.


